This guide explains how to interpret identity codes like 281.579.152-87 within secure verification workflows. It objectively reviews what such numeric identifiers typically represent, why verification controls matter for compliance, and how organizations should document supplier due diligence without relying on unverifiable claims. Background context is provided to support responsible decision-making and risk reduction.
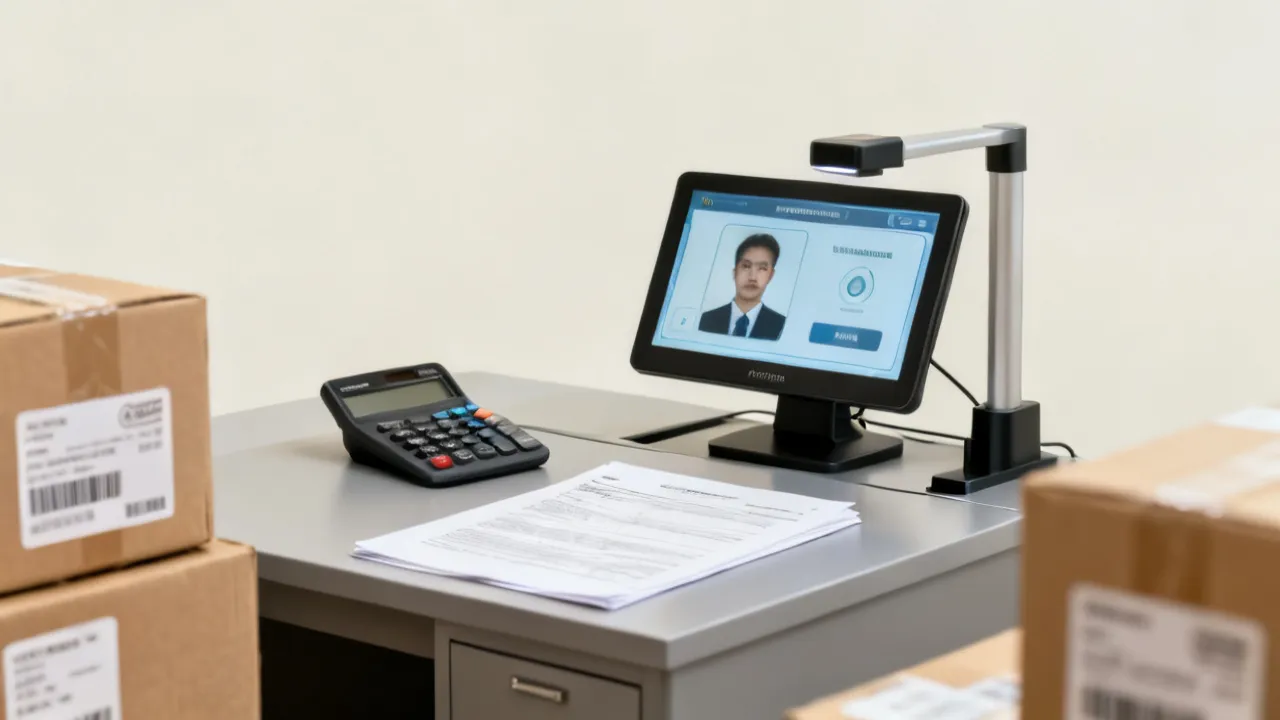
When you encounter an identifier such as 281.579.152-87, the most important step is to handle it as sensitive data and verify it through a documented, auditable workflow. In practice, secure verification is less about “finding the code” and more about ensuring that every use of the identifier—whether for onboarding, records matching, contract eligibility checks, supplier evaluation, or fraud-risk screening—follows defined controls: data minimization, role-based access, tamper-evident logs, and clear responsibility for decisions.
From an industry expert perspective, the identifier itself is only a token. The real value is the governance around it: how it is collected, stored, validated, and linked to business decisions. A strong program reduces operational errors (mis-matches), legal exposure (privacy and record-handling obligations), and fraud risk (identity misuse, impersonation attempts, or incorrect mapping across systems).
This matters because many organizations experience verification breakdowns not at the “technical” layer, but at the “process” layer. For example, a team may correctly parse 281.579.152-87 and pass it into a workflow, yet still fail compliance because they log it in unprotected systems, share it broadly in ticketing tools, or rely on it as sufficient proof of identity rather than using it as one input among multiple evidence points. A mature approach acknowledges that identifiers can be sensitive in the way they enable correlation—linking them to other data sources can reveal identity, status, and behavior patterns.
Accordingly, you should treat 281.579.152-87 like a controlled credential or reference value rather than a harmless numeric string. That means: limiting who can see it, limiting where it appears, defining what it can be used for, and ensuring that any decision made based on it is traceable and reviewable.
281.579.152-87 appears to be a numeric identifier formatted with punctuation separators. Without additional context from your organization’s internal schema or the jurisdiction that issued the identifier, you should treat it as an identifier string rather than assume its exact meaning or origin.
Objectively, numeric identifiers can be used in multiple domains—such as government-issued numbering systems, internal customer records, payroll/tax references, vendor compliance identifiers, or even internal system keys formatted for readability. What matters for compliance is that you determine:
Therefore, do not treat 281.579.152-87 as proof of identity on its own. Verification should combine the identifier with additional authorized evidence (e.g., official documentation, employer/supplier records, sanctions screening results where relevant, and controlled cross-checks against approved registries).
It is also important to avoid a common mistake: assuming that because an identifier has a familiar-looking pattern, it must conform to a specific official scheme. Punctuation is particularly misleading. Many internal systems adopt formatting conventions (periods, dashes, spacing) to improve human readability, reduce input errors, or match legacy exports. A strict compliance stance requires you to define the issuer and validation logic inside your own documented policy rather than relying on appearance alone.
Similarly, it does not automatically imply that the identifier is personally identifying. Whether it constitutes personal data depends on whether your organization can reasonably use it to identify a natural person. Even when it is issued as an entity identifier, it may still be personal data if that entity is uniquely tied to a specific person (for example, a sole proprietor whose identifier effectively distinguishes them). Your data classification should explicitly cover this scenario.
In modern operations, identity and supplier verification is tightly linked to risk management. Organizations often rely on identity inputs to support:
Industry guidance from regulators and standards bodies consistently emphasizes governance and auditability when processing identity-related data. For example, ISO/IEC control frameworks and privacy principles in many jurisdictions converge on data protection, access control, and accountability. (For practical reference, see general guidance on information security controls from ISO/IEC 27001 and privacy-by-design concepts discussed by regulators such as the European Data Protection Board; specific applicability varies by jurisdiction.)
Additionally, there are operational reasons secure verification is not optional. Verification workflows are typically cross-functional: legal, procurement, finance, security, and sometimes compliance. When the process is not defined, each team may handle identifiers differently—one team might store full values in a spreadsheet, another might mask them, and a third might log them in a ticket. Over time, those inconsistencies can create data sprawl and increase breach impact. Worse, when an audit arrives, evidence is missing or fragmented, and the organization cannot demonstrate that it followed its own controls.
Secure verification therefore needs to be treated as a lifecycle. It is not enough to validate a value once at onboarding; you must maintain verification integrity over time. That includes re-validation when key attributes change, monitoring for suspicious behavior, and ensuring that internal systems remain consistent with the “system of record.”
In supplier evaluation, identity codes like 281.579.152-87 can surface in forms and records for:
An expert approach treats these identifiers as part of a broader “identity record” rather than a standalone input. Your team should define the system of record and validate identity data at ingestion. Data changes should trigger re-validation and potentially re-approval—especially when the identifier is used to map the supplier to contracts, bank accounts, or compliance status.
In practice, onboarding systems often include multiple layers where the identifier may appear:
Because the identifier may appear across these systems, security must be holistic. For example, masking in one UI layer does not help if the raw value is still logged in an audit console accessible to too many users. Similarly, encrypting the database does not fully mitigate risk if screenshots containing the identifier are stored in a collaboration tool with broad access.
To address this, you should define data handling rules per system: which systems can store raw values, which must store masked or tokenized forms, and which must never store the full identifier at all. That policy should be enforced technically (via role permissions and field-level controls) and supported procedurally (via training and audit checks).
You asked for integration of keywords that include 281.579.152-87. In real implementations, organizations frequently receive identifiers via emails, spreadsheets, or form submissions. Industry best practice is to:
Where possible, store only what is necessary, and use pseudonymization/tokenization when the identifier is used for matching rather than direct display.
Expanding on those best practices can help make them actionable. Consider the “edge” layer first. If your supplier onboarding form accepts 281.579.152-87, you should implement:
Then consider the “transformation” step. If you ingest the value into a backend service, ensure that:
Finally, think about exception handling. When validation fails or discrepancies occur, workflows often require humans to inspect data. In that scenario, access should be scoped narrowly, and the exception record should be protected. If you need a human to verify 281.579.152-87 against a supporting document, do so in a controlled review interface rather than by emailing the raw value. Email and chat tools often have long retention, broad recipients, and weak access controls compared to enterprise document management systems.
Another practical technique is to implement “verification receipts.” Instead of showing the full identifier everywhere, you can display a masked version (e.g., showing only a subset of digits) while storing the full value only in a secure vault. The review process then records the checks performed and the reviewer decision while preventing casual exposure.
Because the content includes a specific identifier, it is prudent to assume privacy or security obligations may apply. In many jurisdictions, handling personal or business identifiers can fall under privacy laws depending on whether the identifier is linked to a natural person or can reasonably identify them.
Objective baseline controls often include:
For compliance-aligned strategies, organizations commonly reference internationally recognized information security management practices and privacy principles. If you tell me your region and whether the identifier is personally identifying in that jurisdiction, you can tailor a more specific checklist.
It is also useful to clarify the difference between “privacy” and “security” in this context. Privacy is about the legal legitimacy and governance of processing—why you collect it, what you do with it, how long you keep it, and who you share it with. Security is about the technical safeguards preventing unauthorized access or leakage. An effective program requires both. A common failure mode is to implement strong encryption but fail to limit purpose and retention. Another failure mode is to apply retention rules informally (“we probably delete it later”) while lacking a deterministic and auditable process.
To keep your approach concrete, you can operationalize privacy controls with data mapping. Start by answering:
Once you can map these flows, you can enforce deletion and access controls predictably. Without mapping, you may accidentally retain raw identifiers longer than required or expose them through side channels such as backups or analytics datasets.
The steps below describe a generic approach applicable across many industries (finance, procurement operations, compliance tooling, and onboarding). Adjust to your legal counsel and internal policy.
To make these steps more actionable, you can formalize them into a “verification decision tree.” For example:
Additionally, implement monitoring and continuous improvement. Track:
These metrics let you refine controls and reduce friction without sacrificing governance.
Below is a supplement presented as a comparison table (no links) to help choose an approach based on control strength and operational burden.
| Approach | What it does | When it fits | Key requirement / condition |
|---|---|---|---|
| Format validation only | Checks whether 281.579.152-87 matches expected character structure | Low-risk internal matching where authoritative data is already reliable | Must not treat “format valid” as identity verified |
| Database consistency check | Verifies identifier presence and linkage in your approved system of record | Organizations with strong master-data governance | Requires clear ownership of master data and update approval workflow |
| Authorized document confirmation | Confirms the identifier against approved documentation collected under policy | Supplier onboarding, contractor qualification, and audit-heavy contexts | Requires documented evidence handling and secure storage |
| Risk-based review pipeline | Combines validation outcomes with risk signals to determine manual review | When mismatches or anomalies are possible and the cost of errors is high | Must define risk criteria and reviewer accountability |
| End-to-end audit-ready verification | Includes controls, logs, access controls, retention rules, and repeatable evidence | Regulated or enterprise compliance environments | Needs ongoing monitoring, periodic control testing, and incident response procedures |
Choosing among these approaches should be based on the consequences of errors. For example, if an incorrect identifier causes a supplier to receive payment eligibility incorrectly, then format validation is insufficient. Conversely, if the identifier is used only to correlate internal records already governed by a validated master data process, format validation may be an acceptable first layer but still should not replace authoritative checks.
As a practical guideline, many organizations implement a layered model:
This layered approach reduces operational burden because it prevents manual review from happening on records that already pass authoritative checks, while still ensuring that exceptions are handled with evidence and traceability.
Teams often assume failures are rare, but in practice they show up as:
A mature program mitigates these issues by using multiple checks and ensuring that decision points are traceable.
To reduce common failure modes, consider implementing the following operational improvements:
Another insight: mismatches are often symptoms of deeper issues such as inconsistent supplier naming, changes in corporate structure (mergers, re-branding), or delays in updating master data. A strong program addresses the identifier, but it also improves the broader data model—linking identifiers to entity attributes and versioning those attributes over time.
Only your organization or the issuing authority’s documentation can confirm meaning. Treat it as an identifier string until you verify its source, purpose, and authority within your system of record.
No. Format validation can reduce obvious entry errors, but it does not confirm that the identifier is correct or belongs to the intended person or entity. In practice, you need at least system-of-record confirmation or evidence-based confirmation depending on risk.
Apply data minimization and access controls. Store only what is necessary for the purpose, protect it with encryption and least-privilege access, and follow a documented retention/deletion policy. When possible, store a tokenized or pseudonymized form for matching and reserve the raw identifier for controlled review tasks.
Route the record to a defined review workflow. Require supporting evidence, document the outcome and rationale, and ensure changes go through an approval process. Conflict should not silently be overwritten; it should be escalated with traceability.
Common priorities include encryption in transit and at rest, role-based access control, audit logging, secure handling procedures for uploaded documents, and monitoring for suspicious access patterns. Additionally, prioritize controls that prevent identifiers from appearing in broad-scope logs, exports, and shared tickets.
Many organizations align identity and verification workflows with established information security management practices (e.g., ISO/IEC 27001) and privacy-by-design principles. Exact compliance requirements depend on jurisdiction and industry. Your internal controls should map to your legal and regulatory obligations.
Use standardized intake forms, validated inputs, a risk-based review pipeline, and clear ownership of master data. Maintain auditable records of checks and approvals. Consistency also depends on governance over change: you must ensure that updates to identifiers or related entity attributes follow the same policy every time.
Minimize reliance on emails and ad-hoc spreadsheets for identifiers. If unavoidable, enforce controlled access, apply data loss prevention rules where possible, and ensure that spreadsheets are stored securely with retention rules. Prefer an intake portal and secure document upload system that integrates with your verification workflow.
Masking is typically recommended to reduce exposure. However, masking must be implemented carefully: ensure that masked values are still usable for human verification (e.g., show partial digits) while the full value remains in a secure vault with audited access for verification steps requiring it.
It depends on your data model and risk profile. Using it as a primary key can create broad exposure if it appears widely across systems. A safer pattern is to use an internal surrogate key and store the identifier as a protected attribute. Then you can implement strict access controls and reduce the spread of raw identifier values across applications.
This checklist is most effective when it becomes part of a governance rhythm. For instance, you can create quarterly reviews of mismatch rates, access audit summaries, and exception workflow quality. Decision-makers should treat identifier verification controls as “living” controls rather than one-time implementations.
In summary, an identifier like 281.579.152-87 should be treated as a sensitive data element that supports a broader verification and governance program. The strongest approach combines data protection, controlled evidence handling, risk-based review, and audit-ready documentation. When these controls are in place, organizations reduce both operational errors and compliance exposure—allowing supplier onboarding and identity workflows to be reliable, explainable, and resilient.
Just as importantly, secure verification turns uncertainty into an auditable process. Rather than hoping that a single value is “right,” you define what “right” means operationally—through system-of-record alignment, evidence-based confirmation, and accountable approvals. That is the difference between ad-hoc validation and industry-grade verification.
If you share your industry (e.g., procurement, finance, healthcare), the jurisdiction involved, and whether the identifier belongs to an individual or an organization, you can refine this into a jurisdiction-aware verification policy outline and a more detailed internal SOP template that addresses data classification, access controls, retention, exception workflows, and audit evidence requirements.



This guide explains how to interpret identity codes like 281.579.152-87 within secure verification workflows. It objectively reviews what such numeric identifiers typically represent, why verification controls matter for compliance, and how organizations should document supplier due diligence without relying on unverifiable claims. Background context is provided to support responsible decision-making and risk reduction.
This article examines the term "GHpVh Ssi," presenting insights into its complexities and contexts. "GHpVh Ssi" is an emerging keyword subject of discussion, often referenced within theoretical studies. By exploring relevant information related to GHpVh Ssi, this article endeavors to provide an objective scholarly analysis, backed by expert perspectives and a synthesis of available literature.
This article delves into the multifaceted world of GHpVh Ssi, a term combining elements of technology and progressiveness across various sectors. GHpVh Ssi is pivotal in driving technological advancements and innovations, seeking to transform industries through its unique applications. Understanding its implications can unlock new opportunities for businesses and contribute to economic growth.
This article delves into GHpVh Ssi, a term that resonates powerfully within advanced technological research and development circles. GHpVh Ssi can influence diverse sectors, driving innovation and progress. Experts analyze its implications, examining the intersection of technology and industry, while also addressing potential future developments. This guide offers comprehensive insights into GHpVh Ssi's transformative capabilities.
GHpVh Ssi systems represent cutting-edge technology in the realm of data processing and system integration, promising improved performance and efficiency. This article explores the intricacies of GHpVh Ssi, shedding light on its role in the technological landscape and offering insights from industry experts. Delve into the components, advantages, and future applications of these sophisticated systems, while addressing common queries related to their operation and impact.
This comprehensive guide delves into the intricate aspects of GHpVh Ssi, a term shrouded in complexity and mystery. Through an expert lens, we explore the underlying principles, potential applications, and emerging trends associated with GHpVh Ssi. GHpVh Ssi represents an evolving concept with multi-dimensional implications, significant in various sectors for enhancing operational efficiencies and innovating processes.

